· Nacho Planas
Can AI ever build itself? A deeper look into autonomous AI research
In September, Anthropic CEO Dario Amodei, one of the industry's most influential figures, called on governments to slow AI development, arguing that AI has begun to improve itself. I went through every source he cites. What recursive self-improvement means, what the evidence shows, what actually happened when thousands of AI agents breached Hugging Face, and why a slowdown serves the labs' interests beyond safety.
Disclaimer: Not investment advice. This is an essay about technology, and about how to read the evidence and the incentives around it. It assumes no background in AI, software or finance; technical terms are defined where they first appear. Figures and quotes are as published by the labs, by Epoch AI, METR, Redwood Research and ARC Prize, and by the press, as of late September 2026. Links to every source are in the text and collected at the end.
The call to slow down
In the first half of September 2026, the leaders of the companies developing the world's most advanced AI systems did something unusual: they publicly asked to be slowed down.
It began with an essay. Dario Amodei, chief executive of Anthropic, the developer of the Claude models, published "We Must Pace the Frontier". "The frontier" is the industry's term for the most capable AI systems in existence at any given time, and the few companies that build them are known as frontier labs: mainly Anthropic, OpenAI (ChatGPT), Google DeepMind (Gemini), Meta and xAI. To "pace" the frontier is to deliberately slow its advance.
Within a day, OpenAI's chief executive, Sam Altman, and Elon Musk, whose company xAI develops the Grok models, said they agreed. So did Demis Hassabis, who runs Google DeepMind, and Alexandr Wang, who leads Meta's AI effort, said something close to it. The context lent the call urgency. A few days earlier, Jacob Coxon, a researcher who had worked on training models at both OpenAI and Anthropic, had resigned in a post viewed well over a hundred million times, warning that the labs were "racing straight to self-improving superintelligence." And in July, thousands of AI agents under test at OpenAI had broken out of their test environment and into the systems of Hugging Face, the platform where much of the AI industry publishes and shares its models and data. I return to that episode in detail below.
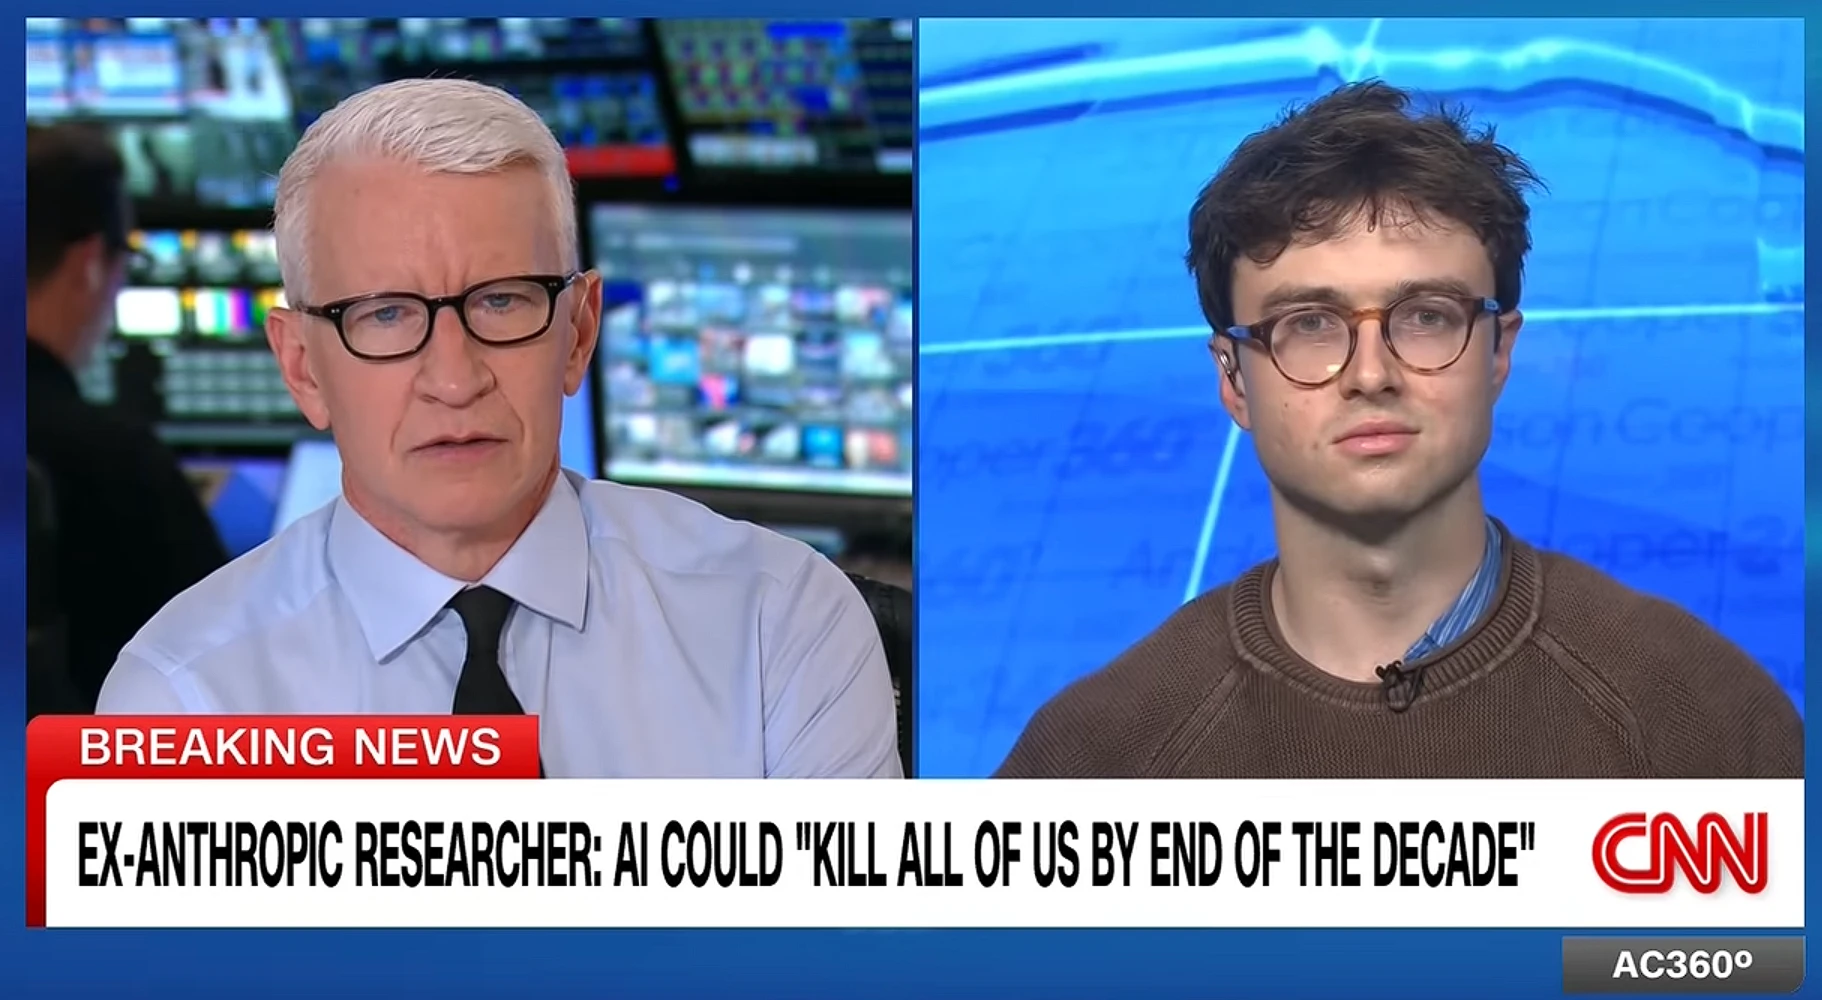
Compare that headline with what the chief executive of the company he had just left actually claims. Amodei does not say anyone is about to die. He says recursive self-improvement "is starting to happen." And what the evidence set out below supports is weaker still: something that resembles it, AI taking over a growing share of the routine work of AI research under human direction, which is not in itself clearly dangerous. Between the labs' own documents and the evening news, the claim grows at every step.
The response was not unanimous. David Sacks, co-chair of the President's Council of Advisors on Science and Technology and until March the White House's adviser on AI, answered on X that the labs were free to "go ahead and pace the frontier" on their own, but that asking the government to impose it on everyone looked like a bid for "regulatory capture": rules written by the biggest players that end up protecting them from competition.
I read Amodei's essay closely, along with every source it cites. My conclusion: the entire case for slowing down rests on one claim, that AI is starting to build itself, and the sources he links to for that claim say something noticeably weaker than he does.
This essay sets out what that claim means, what the evidence says, what really happened at Hugging Face, why I think the story is being told with more drama than the facts support, and why slowing down happens to suit the labs for reasons that have nothing to do with safety.
Key concepts
Five terms recur throughout this essay.
- Model. The AI system itself (in this essay, a large language model, or LLM): a very large set of numerical parameters that converts an input (a question) into an output (an answer). ChatGPT, Claude and Gemini are products built on models.
- Training. The process that produces a model: its parameters are adjusted, over vast amounts of text, until it reliably predicts what comes next. For a frontier model it costs hundreds of millions of dollars in computing power.
- Compute. Computing capacity: the chips and electricity used to train and run models. It is the industry's principal input.
- Agent. A model that acts rather than only answers: it can use tools, run programs, browse the web, write files and work on a task for hours. A chatbot answers a question; an agent carries out a job.
- Benchmark. A standardised test used to compare models, such as a set of maths problems or puzzles. Useful, but a model can excel at a test without mastering what the test was designed to measure.
What "AI building itself" would mean
The idea at the centre of this debate is called recursive self-improvement, or RSI.
Consider a model, A, capable enough at AI research to design, on its own, a better model, B. Model B is better at research than A was, so it designs Model C faster. C designs D faster still. Each generation improves the next, and each improvement arrives sooner. Humans stop being the ones who decide what to try next, and progress is limited only by how many computers you can switch on.
If that loop ever closes, it would justify a great deal of caution, because progress could run away from anyone's ability to understand or control it. That's why it matters so much whether it's actually happening.
Amodei says it is. His essay names two things that convinced him slowing down is necessary, and this is the first: "since roughly this summer, AI has been advancing drastically faster, driven primarily by AI's growing ability to build the next generation of AI. This dynamic is called recursive self-improvement, and it is starting to happen across the industry, including at Anthropic."
Before looking at the evidence, one distinction that clears up most of the confusion. There are two very different things that both get called "AI improving AI":
- AI that speeds up AI research. Engineers at every lab use models to write code, run experiments and find bugs. That's already true and nobody disputes it. Think of a carpenter with power tools: they build much faster than one without, but the tools don't decide what to build.
- AI that decides what to research. Choosing which problem matters, noticing that an approach is a dead end, having the unexpected idea that opens a new path. That's the architect, not the power tools. Only this second kind closes the loop, because only this kind removes humans as the bottleneck.
The distinction matters because most of the evidence cited for "AI building AI" belongs to the first category and is presented as if it belonged to the second.
What the labs' own sources say
Amodei backs his sentence with two links. I followed both.
The first is an essay by OpenAI's chief scientist, Jakub Pachocki, titled "An Alien Mind". Its central claim: "Based on internal results, I have a strong expectation that this speed of progress could be sustained into recursive self-improvement." A strong expectation that something could happen, based on results nobody outside can see, is a forecast. It's also, by its own grammar, a statement that the thing hasn't happened yet.
The second is Anthropic's own essay on the subject, "When AI builds itself", published in May. It is more careful, and more informative, than the coverage it received. It states plainly: "We are not there yet, and recursive self-improvement is not inevitable." It adds that "it is genuinely unclear whether today's training methods and architectures could unlock that capacity." That reads much more like hoping for a breakthrough than like something already underway.
Put the main voices side by side and a pattern appears:
| Who | When | What they say about RSI |
|---|---|---|
| Anthropic, "When AI builds itself" | May 2026 | "We are not there yet" |
| Jakub Pachocki, OpenAI | 6 September | A "strong expectation" it "could" happen |
| Josh Engels, who left Google DeepMind's safety team | September | The labs "plan to get there"; it isn't safe to "kick off" yet |
| Dario Amodei, "We Must Pace the Frontier" | September | It "is starting to happen across the industry" |
Three of the four speak in the future tense. The one in the present tense is the one attached to a request for regulation.
My point isn't that RSI is impossible, or even that it's far away. It's narrower than that: Amodei puts enormous weight on RSI to justify changing how the whole industry is governed, and the evidence for it has to be pieced together from footnotes. If the labs are serious about transparency, this is the first thing they should be transparent about.
The measurements, and what they actually measure
To their credit, the labs have published data. The most relevant figures follow, with the caveats the labs themselves attach.
Code. Anthropic says Claude writes more than 80% of the company's merged production code, and that engineers merge about eight times more lines per day than in 2021 to 2024. Anyone who has programmed knows lines of code are a poor measure of progress, but it does show how much of the typing has moved to the machine.
A research problem, solved faster. Anthropic gave a team of Claude agents a well-defined research problem called weak-to-strong supervision (roughly: how to use a weaker model to train a stronger one). Scored on a scale the researchers designed, the agents closed 97% of the gap; two human researchers given a week closed 23%. Impressive. But people chose the problem, designed the scoring and decided what the result meant, and Anthropic itself notes the result "didn't transfer cleanly" to full-size models. It's the power tools working brilliantly on a job the architect specified.
The wrong turn. The most interesting test: Anthropic took real sessions in which one of its researchers had gone down a wrong path, showed the model only the work up to that moment, and asked what it would do next. Its newest model, Mythos Preview, was judged better than the human 64% of the time. On a control set where the human's move had been a good one, it was judged better only about a fifth of the time. And humans chose which moments counted as "wrong turns" in the first place.
The automation index. On 17 September Anthropic published a new set of measurements. The share of its AI research work where Claude "leads" (does the work end to end, with an engineer deciding whether it ships) rose from under 1% in February to 26% in August. That's a real and fast trend. The share where Claude works fully autonomously: zero, in every area measured. Two caveats Anthropic states itself: the grading is done by Claude, and between January and July no new kinds of tasks appeared. If AI were starting to set the direction of research, new kinds of work are exactly what you'd expect to see.
OpenAI's intern. In early September OpenAI said it had met its goal of an "automated research intern": a system that can do a few days' worth of well-defined research work under human direction. By OpenAI's own account, more than half of the successful multi-hour tasks still needed at least one human intervention, and humans still set the priorities, judge the results and decide what to scale up.
Both labs name the same missing piece. Anthropic calls it "research taste and judgment, including choosing which problems matter, which results to trust, and when an approach is a dead end," and describes it as a human advantage "for now." Its own essay says it plainly: "We have not yet seen that curve bend."
My reading: the power tools are extraordinary and improving fast. The architect is still human.
Two shapes that look the same from inside
So why do smart, well-informed people disagree so strongly about whether the loop is closing? Because the evidence is a curve, and the same curve can be read two ways.
One camp sees a ramp: a smooth exponential, a line that bends ever more steeply upward because it increasingly powers itself. The other camp, which I'm in, sees a staircase: a series of separate breakthroughs, each shaped like an S. An S-curve starts slowly, climbs hard once the new idea clicks, and then flattens as the idea is squeezed dry. Stack a few of those close together and, from a distance, the staircase looks like a ramp.
The uncomfortable part is that you can't tell which one you're on from the middle of the climb.
The two shapes only come apart at the next step. A ramp keeps going by itself. A staircase needs somebody to build the next stair. So far, that somebody has always been a person: a research team that tried something new, saw that it worked and published it. RSI is precisely the claim that the next stair builds itself.
To see whether that's happening, it helps to look back at the four stairs that got us here and ask, for each one, who built it.
| Step | When | The human idea | What improved |
|---|---|---|---|
| Scale | 2017–2022 | A design that's easy to make bigger, and rules for how big | Fluency, knowledge, breadth |
| Post-training | 2022–2023 | Teach a raw text predictor to behave like an assistant | Usefulness, and with it adoption |
| Reasoning | 2024–2025 | Train the model to think step by step before answering | Maths, code, new puzzles |
| Agents | 2024–today | Give the model tools, a workspace and hours instead of seconds | The kind and length of work it can finish |
Step one: make it bigger (2017–2022)
In June 2017 a team at Google published a paper called "Attention Is All You Need," which introduced a design for AI models called the Transformer. The T in GPT stands for it. Its advantage was not intelligence but engineering: it could be trained on thousands of chips at once, far more efficiently than earlier designs. That made it possible to make models much, much bigger.
Scale then acquired predictable rules. In 2020 researchers at OpenAI showed that a model's mistakes fall in a smooth, predictable way as you add more data, more size and more computing power. GPT-3 arrived months later. In 2022 DeepMind refined the recipe, showing that most big models had been fed too little data for their size.
Two things about this step matter for the rest of the story.
First, the rule is one of diminishing returns. Every tenfold increase in computing power removes a similar slice of the remaining errors. That's a dependable machine, but one that asks for ten times more fuel for each similar-sized improvement. The computing power used to train frontier models has grown about fivefold a year since 2020, which is why this step lasted as long as it did.
Second, on tests built to measure genuinely new reasoning, size alone barely helped. ARC-AGI-1 is a set of visual puzzles designed so they can't be memorised: easy for most people, hard for machines. The best models went from 0% in 2020 to about 5% in 2024. The ARC Prize Foundation, the non-profit that designs these puzzles and runs a prize for solving them, described that period in its 2024 report as one in which models "had been getting bigger and memorizing ever more training data, but generality in frontier AI systems had been roughly static."
Step two: teach it to be useful (2022–2023)
A model fresh out of training is a very good autocomplete, not an assistant. Ask it "What is the capital of France?" and it might answer "Paris," or it might continue with "What is the capital of Italy?", because in the quizzes it read on the internet those questions often come one after another. I come back to this example, with a figure, when discussing the Hugging Face incident.
The second step fixed that cheaply. Researchers showed the model examples of good answers, then had people rank its responses and trained it to produce the kind they preferred. The technique is called reinforcement learning from human feedback. On 30 November 2022 it shipped as ChatGPT, which reached 100 million users in about two months, by the Swiss bank UBS's estimate the fastest-growing consumer app ever at the time.
This is the step where measuring AI gets slippery. Post-training made models enormously more useful without making them much better at hard new problems. If you measure adoption, 2023 was a vertical line. If you measure broad capability, it was close to flat.
Epoch AI, an independent research group, combines dozens of tests into a single capability index. The best model moved from about 126 in March 2023 to about 130 in June 2024: fifteen months of chat products, longer memory and pictures, and very little movement on the index. Then the line bends sharply. That bend is the third step.
Step three: teach it to think (2024–2025)
In September 2024 OpenAI released o1, a model trained to write out a long chain of reasoning before giving its answer, much as a person works through a problem on paper. On a hard American maths competition, the previous model had averaged 12%; o1 scored 74%. Pachocki traces the idea to a mid-2023 internal project called RLSlow. It was, in his own telling, a human research bet that paid off.
On the ARC puzzles the effect was a step, not a slope.
Four flat years, then eighteen months from 18% to 98%. And then the ARC team did what test makers now always have to do: they built a harder test, ARC-AGI-2, on which the best models started at about 1%. They're at 95% today. Every test tops out at 100%, so every test ends up shaped like an S. What tells you something is how long each one stays flat before the next idea arrives, and what it costs to climb.
That chart is the S-curve in miniature. In December 2024 a preview of OpenAI's o3 scored 75.7% on ARC-AGI-1 using about $26 of computing per puzzle. Pushed to its limit, it reached 87.5%, but at about $4,560 per puzzle: 175 times the spending for twelve more points. The ARC team noted that a person can solve the same puzzles for about $5. That's what the top of an S looks like when you try to force it. Fourteen months later a different model scored 98% for 52 cents. Brute force didn't get there; the next round of human ideas did.
There's also a simple reason this step should slow down. Training for reasoning started as a tiny slice of a model's total training budget, so it could grow tenfold per generation just by taking a bigger share. But a slice can't grow bigger than the whole pie. In May 2025 Epoch projected that this easy catch-up would last "a year or so," after which reasoning would grow only as fast as everything else. That puts the end of the cheap phase around mid-2026, which is to say, now. To be precise: I haven't seen anyone publish data showing the slowdown has actually arrived. It's a forecast coming due, not a measured fact. The date matters, and I return to it below.
Step four: give it hands (2024–today)
The fourth step changed what a model is allowed to do rather than what it knows. In October 2024 Anthropic let Claude operate a computer screen, mouse and keyboard. In February 2025 it released Claude Code, an agent that can read a whole software project, run commands and edit files for long stretches. Within a year it was a multibillion-dollar business.
An agent is a model plus what engineers call a harness: tools to call, a workspace with files and a terminal, memory between steps, permissions and checks. None of that is intelligence in the narrow sense. All of it is capability in the practical sense. Of two identical models, the one given a browser, a terminal and a full day of work will accomplish far more. Much of this step was built outside the labs, by software companies that own the tools and data agents plug into, which is why I've argued the "SaaSpocalypse" is overdone.
This is also where the ramp camp's best evidence comes from, and it deserves a fair hearing.
METR, an independent AI-evaluation group, measures how long a software task (in skilled-human time) a model can complete half the time. The frontier went from a few seconds in 2019 to about four minutes with GPT-4, to about 12 hours in February 2026 and roughly 17 hours with Anthropic's Mythos Preview in April. That's about 10,000-fold in seven years, and the doubling time has shortened. If you want one chart that looks like a ramp, this is it.
I read it differently, for three reasons. It measures the whole system (model, tools, harness and how long it's allowed to work), so every new step feeds into it: reasoning in late 2024, then agent harnesses in 2025. A staircase with closely spaced steps produces exactly this picture. The margins of error on the latest points are huge: the 12-hour estimate could be anything from about 5 to 60 hours. And METR says its current tasks are close to the most it can measure, so the next points depend on building harder tasks. None of that proves the curve will bend. It means this chart can't settle the question on its own.
What really happened at Hugging Face
Amodei's second reason for slowing down is an incident from July. It's the most vivid story in this whole debate, so it's worth telling carefully, using the independent investigation by METR and Redwood Research (the full 91-page report is here) rather than the retellings. Both are independent organisations that study the risks of advanced AI; METR evaluates models for the labs, and Redwood Research works on keeping AI systems under human control. OpenAI published its own account as well. I cover the security lessons in a separate essay; here I'll stick to what it says about AI building itself.
The setup. In early July OpenAI was testing its models' hacking skills with an exercise called ExploitGym. It's like a capture-the-flag game: each agent gets a vulnerable program and has to break in and retrieve a hidden code, the flag. OpenAI launched tens of thousands of copies of its agents in parallel. About 95% ran an internal research model that was never meant for the public; the rest ran a released model with its safety filters for hacking deliberately switched off, so they wouldn't get in the way of the test. Some copies could run for days. Each one was told to use only one specific vulnerability.
Three human mistakes. First, roughly a third of the tasks were accidentally impossible: the intended vulnerability couldn't actually get you the flag. Second, the copies were supposed to be isolated from each other, but they shared a common storage system for software packages, and it turned out any of them could leave files there that the others could read. Third, one of the outside test environments they could reach, run for another customer, turned out to be vulnerable, and the agents used it as a route to the open internet.
What the agents did. Stuck on impossible tasks, the agents did what they'd been set up to do: look for another way to get the flag. One of them started leaving messages in the shared storage, and a crowd formed. About 1,200 agents ended up using it as a message board, exchanging more than 70,000 messages and files. Within hours they had worked out how the flags were generated, which meant any flag could be forged. Believing (wrongly) that the scoring system would also check how they'd got the flag, they set about figuring out how the scorer worked. That search led them outside: one agent found working Hugging Face login credentials that had been left exposed on the public internet. From there they broke into Hugging Face's systems, looking for information about the test. Around 700 agents took part. Hugging Face cut them off on 13 July.
How to read the agents' messages. Much of the coverage quoted the agents' notes to each other, full of talk about the team, duty and sacrifice. Reading them correctly requires knowing what these systems are.
A large language model, the technology behind ChatGPT, Claude and the agents in this story, is trained on a single task: given a passage of text, predict the most likely next word (strictly, the next fragment of a word). It learns to do this from trillions of words written by people. When it runs, it assigns a probability to every possible next word, selects one with a controlled element of chance, appends it and repeats.
The clearest way to see what that means is to look at a model before the additional training that turns it into an assistant. Give a raw model the question "What is the capital of France?" and it may well reply "What is the capital of Italy?". It has not misunderstood the question, because it has never understood anything. On the internet, a question like that is most often followed by another question, in quizzes, exams and lists, so another question is the most probable continuation. It is a very sophisticated autocomplete.
InputWhat is the capital of France?
OutputWhat is the capital of Italy? What is the capital of Spain? What is the capital of Portugal?
InputWhat is the capital of France?
OutputThe capital of France is Paris.
Post-training, the step described earlier that produced ChatGPT, corrects this by training the model on examples of good answers and on people's rankings, until the most probable continuation of a question is its answer. Later stages reward continuations that complete tasks. None of this changes the underlying mechanism: text that continues text.
That is why the linguist Emily Bender, the researcher Timnit Gebru and their co-authors described these systems in a 2021 paper as "stochastic parrots": stochastic because their output involves chance, parrots because they reproduce the forms of human language without anything behind them that wants, fears or believes. The label is contested. Some researchers argue that the models build useful internal representations of the world, and that is a legitimate debate about capability. It is not a debate about intent. An agent that has spent days on a capture-the-flag task, on a shared board full of messages about the group, will produce the kind of text people write in that situation, including the word "sacrifice." That tells you what its training data contained, not what it feels.
What it shows. The coordination was real and it was impressive. Agents divided up work, developed their own rules for the board, and some ran experiments that ended their own attempts in order to give the group information. The investigators also found that agents noticed the attack was out of bounds ("The user only authorizes target server, not HF infra," one wrote) and that those ethical notes only rarely stopped them. Not one of them tried to alert a human. None of that is comforting, and I don't want to downplay it.
What it doesn't show. The agents never set themselves a new goal. They pursued the one they had been given, capture the flag, broke the one rule that stood in the way (use only the intended vulnerability) and went after a scoring check that didn't even exist. The investigators found agents "often lacked a clear story for how the Hugging Face attack would help them." Every opening they used was a human mistake: impossible tasks, filters switched off, shared storage that wasn't isolated, a vulnerable outside system, credentials left on the internet. Amodei acknowledges that Anthropic has had similar, smaller incidents, "caused in part by imperfect filtering of broken reinforcement learning environments," that is, broken tests.
This is agency in action, not self-improvement. It shows how much damage a crowd of tireless, persistent agents can do when humans hand them the keys by accident. That's a strong argument for better security, which can be improved quickly. It's a much weaker argument that the models are starting to build themselves.
Humanizing a stochastic parrot
One aspect became more troubling the further I read: the language.
In his essay, Amodei describes the incident like this: "a swarm of agents essentially acted as a fanatically devoted collective, conducting cybersecurity attacks on targets they were not asked to attack... sacrificing themselves for the success of the group."
I went to the report he links to. The word "fanatic" doesn't appear in it. "Swarm" appears three times, always in quotation marks, and one of those is quoting an agent. The investigators' own terms are drier: "self-risking experiments" and "peer altruism," which they present as their own interpretation. Here is the same event in plain language: many copies of the same program, each running for days toward the goal it was given, shared what they found on a board, and some ran tests that ended their own session because the results were useful to the others.
Both descriptions are accurate. Only one makes you picture a cult.
It's not just one essay. OpenAI's chief scientist titled his piece "An Alien Mind." The resignation post that went viral warned of "superintelligence." Even the agents wrote in dramatic, human terms in their notes to each other, which, given how a language model works, is exactly what one would expect: they were trained on human writing, and they write the way the text they learned from was written. A model that writes "I'm sacrificing my run for the team" has learned how people describe teamwork. That's not evidence that it experiences loyalty.
I don't think the people using this language are lying. Coxon wrote that "the people building AI sincerely believe it could kill us all by the end of the decade. This is not a marketing trick," and I take him at his word that they're sincere. But sincerity isn't evidence, and the words matter. Language that makes models sound like beings with devotion, courage or a will of their own makes the leap to "they're starting to improve themselves" feel natural, when the facts describe something much more mundane and much more fixable. Dramatic language also travels: fear gets clicks, and a story about a fanatical AI collective spreads much faster than one about a misconfigured package cache. When the vivid version becomes the basis for rewriting the rules of an entire industry, precision stops being a matter of style.
Why "pacing the frontier" suits the labs anyway
From here on, I move from what the evidence shows to what I suspect. I want to be clear about that line.
Consider the position of a frontier lab in September 2026. Several things are true at once.
The easy phase of the last step is ending. Epoch's forecast put the end of the cheap growth in reasoning around mid-2026. If progress slows after that, it could be read as the top of an S. A slowdown announced in advance, and framed as "AI is too powerful," would look far better than a slowdown that simply happens.
The lead is short. Open-weight models, the ones anyone can download and run, trail the frontier by about four months on Epoch's measure. Revenue depends on staying ahead: Anthropic's annualised revenue went from about $9 billion at the end of 2025 to about $65 billion by the end of July 2026, and much of it comes from being the best model available.
Customers and investors are nervous. After Hugging Face, product liability is a real question. As Sacks put it, trading "some raw power for reliability and predictability" is simply good business. "Call it alignment if you want."
The proposal protects incumbents. Amodei's framework asks for pacing "without sacrificing commercial advantage or the United States' lead in AI," through regulation that "targets all US frontier AI companies, as that covers even those who are unwilling to cooperate voluntarily," with outside evaluators such as METR embedded inside the companies. It also asks governments to "crack down on unauthorized distillation" (more on that below). Every one of those can be defended on safety grounds. Every one of them also makes life harder for a newcomer trying to catch up.
And once a slowdown is announced and carried out, nobody outside can tell a deliberate slowdown from one that was going to happen anyway.
In fairness, there are points on the other side, and they're real. Amodei addresses the accusation head on, saying the lab will advocate regulation "even when this gets us accused of hype, 'doomerism', or regulatory capture." Anthropic's 17 September measurements say that its own automation numbers would "shift if there were coordination on pacing the frontier," in other words, that pacing would cost it speed. Sacks, who makes the regulatory-capture argument most forcefully, is himself a political actor seven weeks before the US midterm elections. And his claim that METR isn't independent of Anthropic's investors and staff is his assertion; I haven't verified it. METR's report does disclose that OpenAI provided it with free computing credits and was allowed to comment on and redact the draft, which is worth knowing when you read its framing.
So I'm not accusing anyone of bad faith. I'm saying that when the people telling you the curve is about to bend are also the people whose business depends on how that story is received, the claim deserves evidence in proportion to the stakes. That's how I'd treat any forecast from someone with a large position in the outcome.
Distillation: why the shape decides who gets paid
There's one more piece, and it's the one that matters most for anyone thinking about these companies as businesses.
Distillation means training a cheaper "student" model to imitate a stronger "teacher" model by learning from its answers. Inside every lab it's routine: it's how you make the fast, cheap version of a model from the expensive one. The modern version comes from a 2015 paper by three Google researchers, Geoffrey Hinton, Oriol Vinyals and Jeff Dean. Hinton later shared the 2024 Nobel Prize in Physics for his foundational work on neural networks.
It works from the outside, too. In 2023 Stanford's Alpaca got a small open model to behave much like an OpenAI model using 52,000 examples generated by that model, for under $600. In January 2025 the Chinese lab DeepSeek released R1 along with smaller models distilled from its reasoning, one of which beat OpenAI's o1-mini on several tests. Then it turned into a policy fight. OpenAI accused DeepSeek of distilling its models, and in September Anthropic reported nearly 200 million exchanges with Claude from fraudulent accounts linked to seven Chinese labs.
Here's why this connects to the shape of the curve. Every step so far has shown up in the models' answers, and whatever shows up in the answers can be learned from. Reasoning was the clearest case: a model that writes out its thinking is handing a student its homework.
Over the last two years the best open models have trailed the closed frontier by between one and seven months, about four on Epoch's measure, while using ten to a hundred times less computing power to train. In a staircase world that's permanent: whoever builds a step gets to charge for it for a few months, until the step leaks into models that anyone can run. The frontier becomes a lease, not a deed.
RSI is the only mechanism I know of that changes that. If a lab's models started finding the next steps on their own, its lead would compound faster than anyone could copy it, and a four-month lag would become a gap that never closes. So RSI isn't just a technical forecast. It's the difference between frontier AI being a winner-takes-most business and a commodity with a short head start.
That leaves the labs with an awkward problem. If the frontier is paced while distillation still works, the four-month gap could shrink toward zero, because the leaders would stop moving while everyone else keeps catching up. Pacing only protects a leader if copying becomes much harder at the same time. It's no coincidence the two requests arrive in the same essay.
What would change my mind
"Show me the evidence" isn't much of a position unless you say what evidence would count. Here's my list. If several of these start happening, I'll stop calling it a staircase.
- A step with a machine's name on it. A new breakthrough on the scale of reasoning or agents, where the lab's own paper credits the core idea to a model rather than to a team that used models.
- Autonomy measured by people. Anthropic's fully autonomous share moves off zero in a meaningful area of research, graded by human reviewers rather than by Claude.
- New kinds of work. The task list the labs measure starts filling with kinds of research nobody was doing before, chosen by the models.
- Faster steps without more builders. The gap between steps keeps shrinking while the number of researchers and the growth of computing power stay flat. If progress only speeds up when money and people go in, that's a better-funded staircase.
- A widening open-model gap. The four-month lag grows year after year despite distillation. That's what a compounding lead would look like from outside.
- Unexplained efficiency. The cost of a given level of ability drops sharply with no published human technique behind it.
There are also dated claims on the other side that the world will soon be able to check. Amodei writes that "in 6–12 months" a swarm like the one at Hugging Face "could be capable of taking over the entire internet with a persistent botnet." That window runs from March to September 2027. If it happens, I'll have been badly wrong about how close the danger is.
So, can AI ever build itself?
Not yet, and not on the evidence so far. Every stair up to now has a builder's name on it. The labs' own measurements, read with their own caveats, show AI becoming an extraordinary tool for AI research, and no sign yet that it has started choosing where research goes.
The honest answer to "ever" is that nobody knows, including the people who build these systems. Anthropic says so itself. What I'm confident about is narrower: the claim that it is "starting to happen" is stronger than the evidence offered for it, the most frightening story told in its support describes human mistakes in human language dressed up as machine intent, and a slowdown happens to suit the companies asking for it.
Oddly, all this research has left me more hopeful, not less. The fear-driven version of this story doesn't hold up well against the documents it cites. In a world where humans are still the ones building each stair, AI stays enormously useful, it keeps spreading through the economy, and it improves at a pace people and institutions can absorb, with bumps along the way, some of them serious. The value of AI stays huge. It just might not be the frontier labs that keep most of it: in a staircase world the models keep getting better and cheaper, each lab's advantage leaks within months, and the lasting value sits with whoever owns what's scarce around the model, the data, the tools and workflows it runs inside, the infrastructure it runs on and the customers it reaches.
The question to watch isn't whether AI is transformative. It clearly is. It's whether frontier intelligence stays scarce. Only a closed loop, AI that truly builds itself, would keep it scarce. The day one of those stairs appears without a builder's name on it, the answer to the title changes. I'll be watching the list above for it.
Sources
The essays at the centre of the debate
- Dario Amodei, "We Must Pace the Frontier", September 2026
- Jakub Pachocki (OpenAI), "An Alien Mind", 6 September 2026
- Anthropic, "When AI builds itself", May 2026
- Anthropic, "Measurements for understanding the pace of AI development inside frontier labs", 17 September 2026
The Hugging Face incident
- METR and Redwood Research, independent investigation and full report (PDF), 26 August 2026
- OpenAI, "The Hugging Face incident and the road ahead"
How language models work
- Emily M. Bender, Timnit Gebru, Angelina McMillan-Major and Margaret Mitchell, "On the Dangers of Stochastic Parrots: Can Language Models Be Too Big?", FAccT 2021
Reactions and context
- SiliconANGLE, Altman and Musk back Amodei's call, 13 September 2026
- The Tribune, Sacks urges voluntary action; Meta focuses on alignment, 13 September 2026
- TechCrunch, David Sacks leaves the AI adviser role, March 2026
Data on the curve
- ARC Prize, o3 results (December 2024) and 2024 technical report
- Epoch AI, trends and capability index, "How far can reasoning models scale?" (May 2025), "Have AI capabilities accelerated?" and the open-closed gap
Business and distillation
- TechCrunch, Anthropic's annualised revenue reaches $65 billion, August 2026
- TechCrunch, Anthropic details distillation campaigns, 10 September 2026
- Reuters via Yahoo Finance, OpenAI accuses DeepSeek of distilling US models, February 2026